AI Agent Incident Response: What Business Professionals Must Learn Before Digital Coworkers Go Wrong
By Melverick Ng | Published | Updated | 9 min read
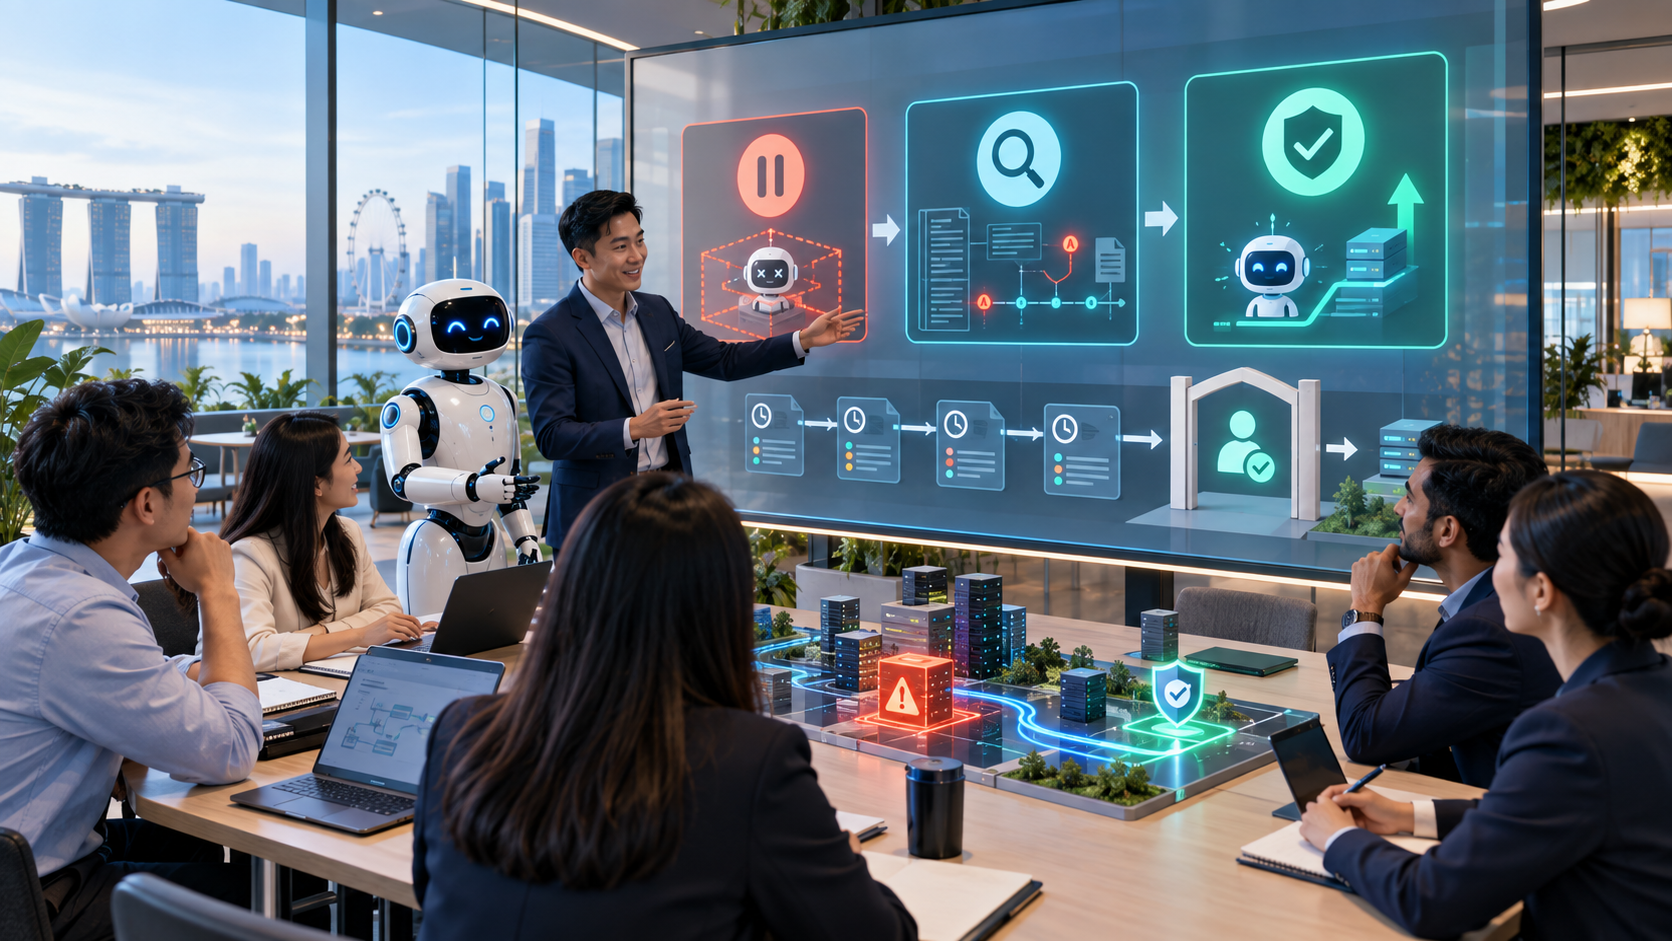
Building an AI agent is becoming easier. Recovering safely when one goes wrong is becoming a workplace skill.
The market is moving in that direction. Okta's latest agent-security framework adds a fourth operating question—“How do I respond?”—alongside discovering agents, defining what they can do, and monitoring what they are doing. WSO2 now offers real-time suspension and lifecycle controls. Lumos is moving policy checks to the moment before an MCP tool call executes. IBM is previewing distinct agent identities and end-to-end auditability.
The learning implication is direct: an AI agent course in Singapore should teach more than prompting and workflow building. Business professionals need to recognise an incident, contain it, preserve evidence, assess business impact, and restore the workflow without hiding what happened.
A Kill Switch Is Not an Incident Plan
Stopping an agent prevents new governed actions. It does not reverse an email already sent, restore a record already changed, or explain which downstream systems were affected. A complete response has three distinct jobs: contain the current risk, reconstruct what happened, and recover the workflow under tighter control.
These are not purely technical duties. Operations, finance, sales, HR, and service teams understand which outcomes matter, which records are authoritative, and which commitments cannot be silently undone. Domain experts therefore belong inside incident design—not only at the end as reviewers.
1.Recognise the Incident
An incident is not limited to a dramatic security breach. It can be a digital coworker using an unapproved tool, processing the wrong customer segment, repeating an action, exceeding a value threshold, exposing sensitive context, or continuing after its human owner has left the process.
Define observable triggers before deployment: repeated permission denials, unusual tool-call volume, missing approval evidence, output outside the declared mission, suspicious input, cost spikes, or a mismatch between the agent's version and the approved workflow.
2.Contain Without Creating More Damage
Containment may mean pausing the workflow, revoking short-lived tokens, terminating active sessions, blocking a connector, removing a queue item, or switching the agent into read-only mode. The response should be proportional to the blast radius.
Assign one incident owner. Record who can pause the agent, who can disable access, and who decides whether customer, financial, production, or privacy stakeholders must be informed. “Someone in IT will stop it” is not an operating procedure.
Next Step
Download the SME Workflow Checklist
Get the exact checklist we use to spot high-ROI automation opportunities in under 15 minutes.
3.Preserve an Evidence Packet
Do not delete the record simply because the agent has been stopped. Preserve the business chain of evidence: triggering request, agent identity and version, human principal, declared mission, data consulted, tool calls, authorization decisions, approvals, outputs, timestamps, errors, and downstream results.
You do not need private model reasoning. You need enough operational evidence for another person to answer: what was requested, what the system allowed, what actually happened, and what remains uncertain?
4.Assess Business Impact
Trace affected records, people, systems, and commitments. Separate proposed actions from completed actions. Check whether another agent or automation continued the chain. Identify what can be reversed, what requires correction, and what requires a human conversation.
- Data: Was sensitive information read, copied, changed, or sent?
- Transactions: Were records, orders, payments, or permissions altered?
- Customers: Was an external message or commitment made?
- Operations: Did a downstream workflow continue from a bad input?
- Governance: Which control failed, was bypassed, or was never defined?
5.Recover in Stages
Recovery should not mean switching everything back on. Start with the smallest safe mode: replay the failed case in a sandbox, verify the corrected rule, restore read access, test one bounded action, require human approval, and watch the telemetry before expanding authority.
Document who approved restoration, which agent version returned, which permissions changed, and which acceptance test passed. If the team cannot show that evidence, the workflow is not recovered; it is merely restarted.
6.Turn the Incident Into a Better Skill
Convert the lesson into a reusable instruction, test, approval rule, monitor, or runbook. This is how digital coworker operations improve: do the work once, capture the evidence, strengthen the skill, and use the improved version next time.
Track time to detect, time to contain, affected actions, reversibility, review effort, and recurrence. The goal is not a perfect incident-free story. It is a system that exposes failure quickly and recovers without losing accountability.
Next Step
Check Your SkillsFuture Subsidy
See your estimated net payable fee and eligibility path in under 60 seconds.
Check My SubsidyRelated Course Module
Module: Build Your First Agentic Workflow Blueprint
Learn how to map, automate, and test one real workflow from your own business during class.
See module detailsRun a 30-Minute Tabletop Drill
Choose one agent-assisted workflow and simulate this event: the agent used a valid credential but attempted the wrong action on ten customer records. Give the team this checklist:
Detect: Which signal reveals the problem?
Own: Who becomes incident lead?
Contain: What is paused, revoked, or isolated?
Preserve: Which evidence must remain available?
Assess: Which records and people are affected?
Recover: What test must pass before authority returns?
Improve: Which rule, monitor, approval, or skill changes?
The next AI skill is not only directing digital coworkers. It is knowing how to regain control when reality does not follow the plan.
Sources
- Okta: Runtime visibility, Agent Gateway, and expanded kill-switch plans
- WSO2: Agent Manager general availability and real-time suspension
- Lumos: MCP governance at the point of action
- IBM: Agent Identity and end-to-end auditability in watsonx Orchestrate
About the Trainer
Melverick Ng is Founder of Nexius Labs and Master Trainer at Nexius Academy. He has trained business teams and non-technical professionals to design practical AI workflows for sales, operations, and customer support.
Talk to a Course Advisor